Industrial AI
Edge AI vs cloud AI in manufacturing
Compare edge and cloud AI for a factory application. Check decision timing, network dependence, data movement and the work of updating models.
Edge AI runs model inference near the equipment or other source of data. Cloud AI runs it on remote computing services. Inference means using an already trained model to produce an output.
Training and inference do not have to happen in the same place. A team can train centrally and deploy a model to a device, while retaining selected monitoring records elsewhere.
NVIDIA's edge AI explanation describes this placement near the data. For a factory, the choice should follow the decision deadline and the dependencies the operating team can support.
Draw the path to the decision
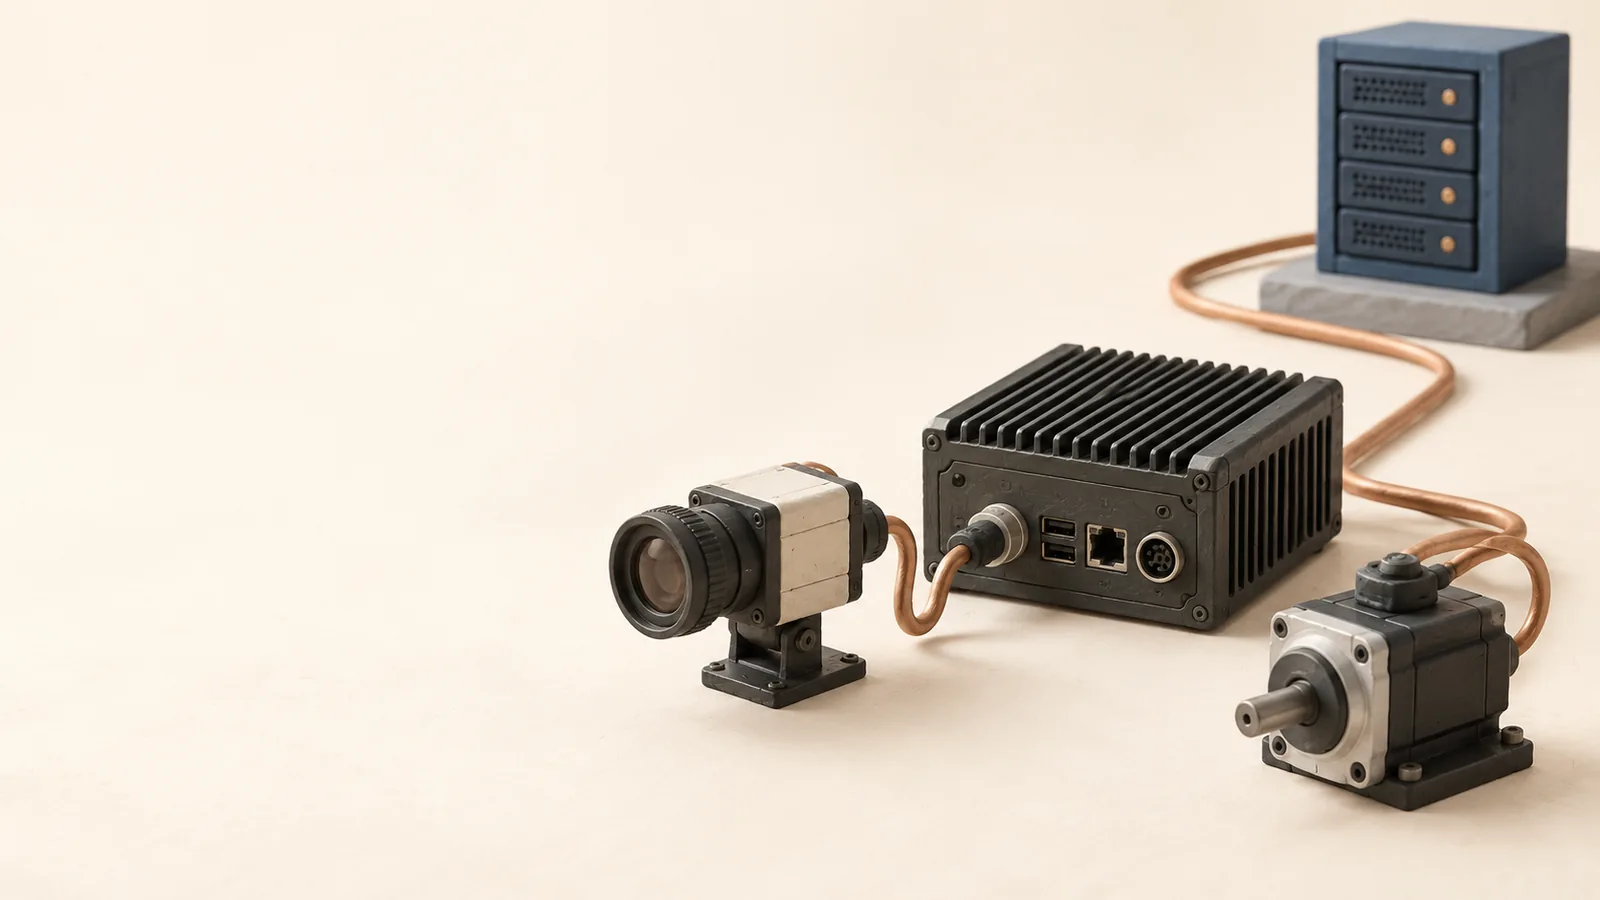
The machine-vision comparison follows image capture, analysis, part tracking and the physical response. Moving analysis to the cloud adds a network path. Keeping it locally leaves a local computing device to maintain.
Neither path removes the rest of the inspection system.
| Question | Local inference | Remote inference |
|---|---|---|
| What must be available for each decision? | Local device, inputs and application | Inputs, connection, remote service and return path |
| What happens during a connection loss? | Local prediction may continue if its dependencies remain available | The design needs a response for missing or late remote results |
| Where does data travel? | Depends on logging, monitoring and update design | Inputs or derived data must reach the remote service |
| Who supports a model update? | Device deployment and local compatibility need checks | Central release still needs compatibility with the site application |
Measure the actual deadline
The word real-time does not state a deadline. Identify when an output must arrive for the equipment or person to use it. Include capture, preprocessing, transmission, inference and the downstream action.
Test the complete path under the relevant load and failure conditions. An average inference time excludes delays elsewhere and can conceal slow decisions.
The batch and stream processing Note helps distinguish continuous data handling from a guarantee about response time.
Check the data boundary explicitly
Local processing can reduce the data sent away for each prediction. It does not establish that nothing leaves the site. Images, logs, model updates and support records may follow separate paths.
Document those paths and access rights. Likewise, a remote service's location does not on its own establish how data are retained or who can access them.
Keep both designs maintainable
Local devices need supported software, a deployment method and a recovery plan. Remote services need a working site integration and an agreed response when communication fails. The MLOps guide follows those continuing responsibilities.
Before choosing, put the two complete designs beside the same decision deadline, outage response and data requirements. Price and test the design the plant will operate, including the work needed to keep its model current.